Workflow status: everything that you see here should be working and has been tested with both Illumina and PacBio tutorial data.
Introduction
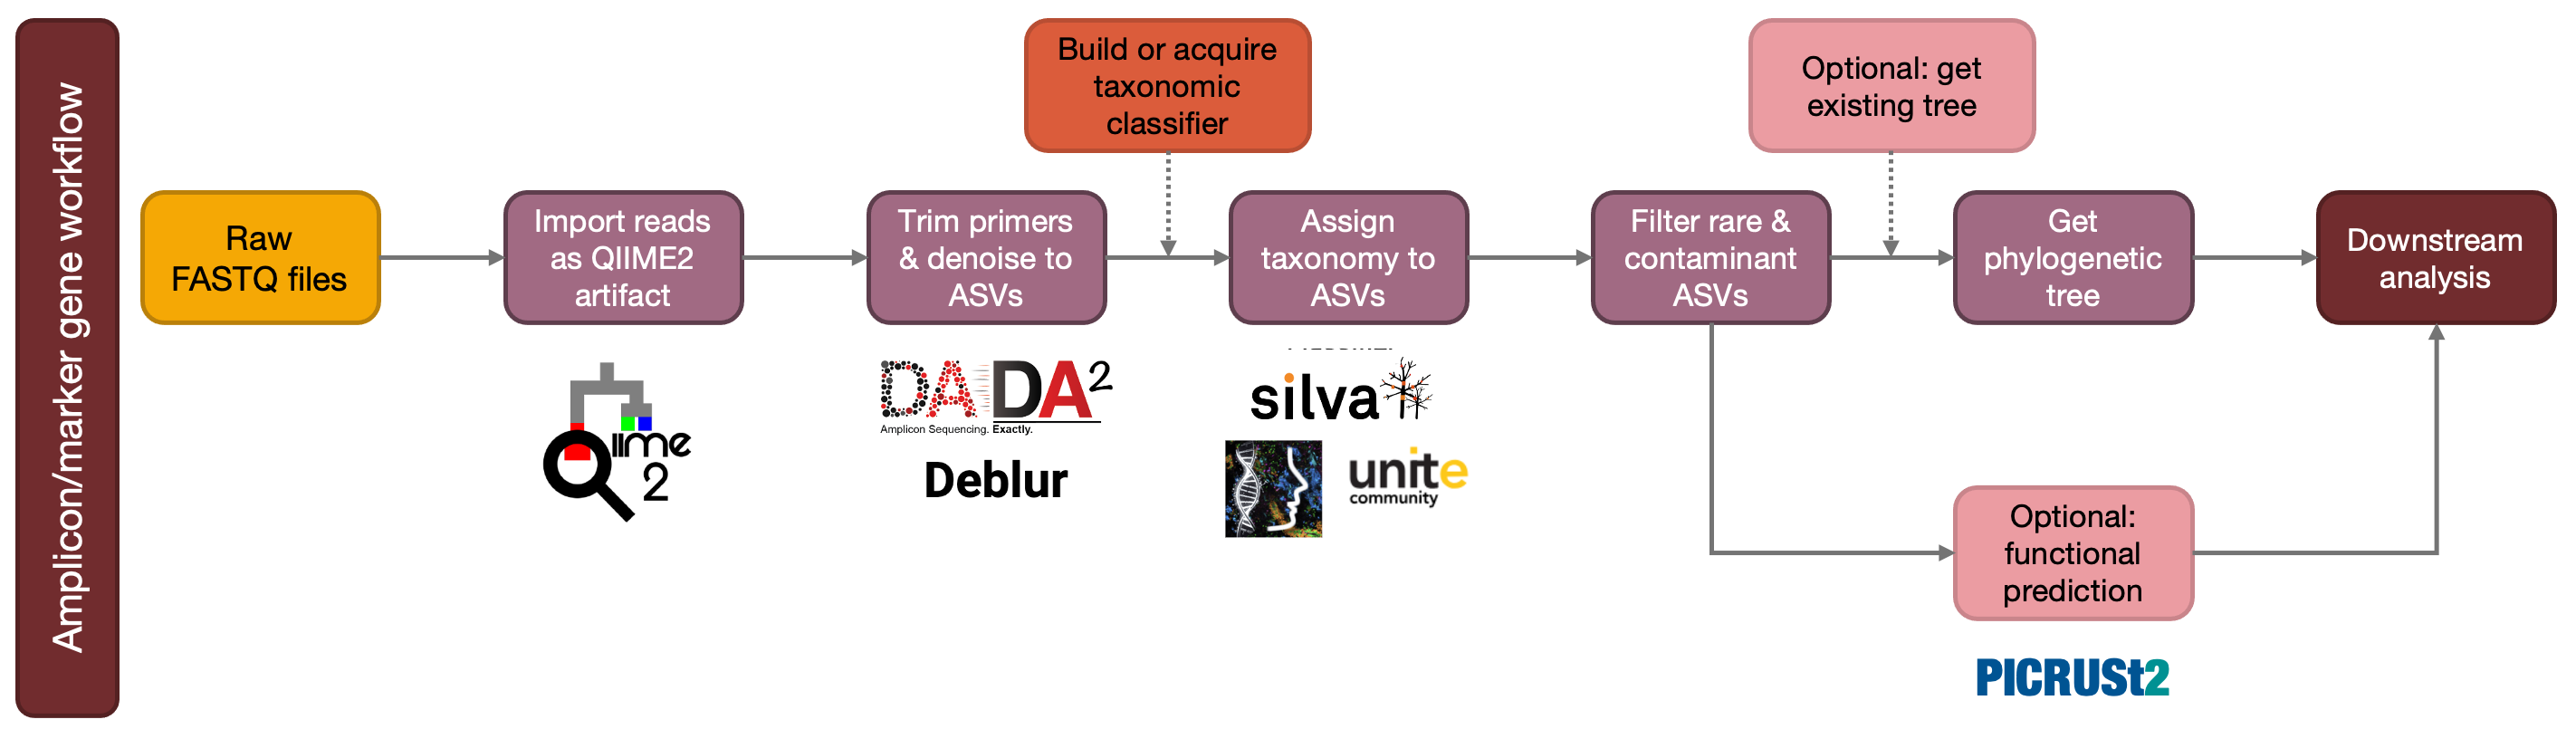
In this workflow, we will go from our raw reads (as they come off a sequencer), and take these all the way through to denoised Amplicon Sequence Variants (ASVs), a feature table containing representative sequences, and a phylogenetic tree.
The pipeline described is embedded in the latest version of QIIME2 (Quantitative Insights into Microbial Ecology version 2026.7 at the time of writing), which is a popular microbiome bioinformatics platform for microbial ecology built on user-made software packages called plugins that work on QIIME2 artifact or QZA files. Documentation for these plugins can be found in the QIIME 2 user documentation, along with tutorials and other useful information. QIIME2 also provides interpretable visualizations that can be accessed by opening any generated QZV files within QIIME2 View.
Many steps in this workflow are the same whether you have sequenced your samples using Illumina or PacBio. The steps that differ are split to Illumina/PacBio.
If you use this workflow make sure to keep track of the commands you use locally as this page will be updated over time (see “history” in the Github code for earlier versions).
Requirements
We are assuming here that you are already familiar with the command line and can install QIIME 2 for yourself. You will need the following conda environments:
rachis-qiime2-2026.7- an environment containing the 2026.7 version of QIIME 2quality_control_sep2026- environment containingfastqcandmultiqc
See our server setup tutorial for more information.
Tools used
Core:
- QIIME 2: Throughout
- FastQC: Initial quality control
- MultiQC: Initial quality control
- Scikit-Learn: Taxonomic classification
Optional:
- Cutadapt: Illumina only section 2.4.1
- Deblur: Illumina only section 2.4.1
- DADA2: PacBio only section 2.4.2
- SEPP: If using the insertion tree method section 5.1
- MAFFT: If using the tree-building method section 5.2
- FastTree: If using the tree-building method section 5.2
- PICRUSt2: If running the functional prediction section 6
- ANCOM: If running differential abundance section 7.5
- Gemelli: If running the phylogenetic RPCA section 7.6
QIIME2 basics
To standardize QIIME 2 analyses and to keep track of provenance (i.e. a list of what commands were previously run to produce a file) a special format is used for all QIIME 2 input and output files called an “artifact” (with the extension QZA). In many of these steps, we will also create QIIME 2 files that can be viewed on their QIIME 2 View webpage (with the extension QZV).
1. First steps
It is assumed that you already have a folder containing your raw data that is called
raw_data/. This will contain either single- or paired-end reads. I would recommend creating this inside a folder that describes your project.
It is also assumed that these reads are in demultiplexed FASTQ format. QIIME 2 accepts many different formats so if your files are not already in this format (e.g. not demultiplexed) you would just need to use slightly different commands for importing your data.
If you don’t have your own data and want to work through this, we have some data available here, or you can find 18S and ITS data available with our tutorials here.
1.1. Set number of cores
Several commands throughout this workflow can run on multiple cores in parallel. How many cores to use in these cases will be saved to the NCORES variable defined below. We set this variable to 1 below, but you can change this to be however many cores you would like to use.
export NCORES=1
1.2. Inspect read quality
Visualize sequence quality across raw reads. This is important as a sanity check that your reads are of reasonable quality and to determine how your reads should be trimmed in downstream steps. QIIME 2 comes with a plugin for visualizing read quality, which we will use at a later step. However, when dealing with raw reads the easiest method to use is a combination of FASTQC and [MultiQC][(https://github.com/multiqc/multiqc).
Activate the environment with fastqc and multiqc installed:
conda activate quality_control_sep2026
This is an important step for identifying outlier samples with especially low quality, read sizes, read depth, and other metrics, and it is useful to do this before running anything else.
Note that we don’t actually show the steps for removing any samples here. There are other steps later on where low-quality sequences will be removed, however, if a large number of your samples show very low quality here, this may be an indication that something went wrong with your sequencing and you may want to investigate this further before carrying on with your analysis.
You can run FASTQC with this command (after creating the output directory).
mkdir fastqc_out
fastqc -t $NCORES raw_data/*.fastq.gz -o fastqc_out
If you receive the error Value "FASTQ" invalid for option threads (number expected) (where “FASTQ” is an input filename) then make sure you have defined the NCORES variable correctly and re-run the command.
FASTQC generates a report for each individual file. To aggregate the summary files into a single report we can run MultiQC with these commands:
multiqc fastqc_out --filename multiqc_report.html
The full report is found within multiqc_report.html. You can view this report in a web-browser on your local computer. The most important reason to visualize this report is to ensure that your samples are of high-quality (based largely on whether the per-base quality is >30 across most of the reads) and that there are no outlier samples.
Remember that you can use the scp command to download these files to your local computer. See the cheatsheet for more information.
2. Import, trim primers, and denoise
2.1. Import FASTQs as QIIME 2 artifact
Choose one of these!
Either import with the expected Illumina format or import with a manifest file.
If your file names within raw_data follow the expected Illumina format (described below), then you can just import them using the QIIME 2 command. If not, then you should follow the instructions for importing them using a manifest file.
Expected Illumina format: 105CHE6WT_S325_L001_R1_001.fastq.gz, where each field separated by an _ character corresponds to:
- The sample name (105CHE6WT)
- The sample number on the run (S325)
- The lane number (L001)
- The read number (R1 for forward and R2 for reverse)
- The set number (001)
Either way, you will need to activate your QIIME2 environment:
conda activate rachis-qiime2-2026.7
2.1.1. Importing with the expected Illumina format
Import the raw reads as a QZA file.
mkdir reads_qza

qiime tools import \
   --type SampleData[PairedEndSequencesWithQuality] \
   --input-path raw_data/ \
   --output-path reads_qza/reads.qza \
   --input-format CasavaOneEightSingleLanePerSampleDirFmt
Then go straight to 2.2.
2.1.2. Importing with a manifest file
If your samples are not in this expected Illumina format, you can use a manifest file to import them. This just a file that tells QIIME 2 what the path to the files is as well as what each of the samples should be called.
We have made a script that makes this file for you if you don’t have it. Skip to the import step if you already have one.
First, download the make_manifest.py script:
wget http://kronos.pharmacology.dal.ca/public_files/MH2/scripts/make_manifest.py
There are then two different ways to run this, you can either run it with just the folder that contains your reads and an output file name:
python make_manifest.py -f raw_data/ -o PacBio_manifest.txt --pacbio
Or:
python make_manifest.py -f raw_data/ -o Illumina_manifest.txt
With a metadata file. The first column of this should contain the sample names that match the file names for your reads. If you also include a column called sample_rename, it will rename the samples when QIIME2 reads them in to the names that you give it.
python make_manifest.py --f raw_data/ -m arctic_study_metadata_illumina.txt -o Illumina_manifest_metadata.txt
Or:
python make_manifest.py --f raw_data/ -m arctic_study_metadata_pacbio.txt -o PacBio_manifest_metadata.txt
Import the raw reads as a QZA file.
With paired-end data (i.e. forward and reverse reads):
mkdir reads_qza

qiime tools import \
 --type 'SampleData[PairedEndSequencesWithQuality]' \
 --input-path Illumina_manifest.txt \
 --output-path reads_qza/reads.qza \
 --input-format PairedEndFastqManifestPhred33V2
With single-end data (e.g. PacBio or other formats where the reads have already been joined or only a single read is sequenced):
mkdir reads_qza

qiime tools import \
 --type 'SampleData[SequencesWithQuality]' \
 --input-path PacBio_manifest_metadata.txt \
 --output-path reads_qza/reads.qza \
 --input-format SingleEndFastqManifestPhred33V2
2.2. Check the imported .qza file
All of the FASTQs are now in the single artifact file reads_qza/reads.qza. This file format can be a little confusing at first, but it is actually just a zipped folder. You can manipulate and explore these files better with the qiime tools utilities, e.g.:
qiime tools peek reads_qza/reads.qza
2.3. Summarize raw FASTQs
It is often useful to check that the files have imported as we expected. QIIME 2 has some helpful QIIME 2 view files (see above) that we can use to check the number of samples that we’ve imported, as well as the number of reads that we have in them.
qiime demux summarize \
   --i-data reads_qza/reads.qza \
   --o-visualization reads_qza/reads_summary.qzv
You can run the demux summarize command on any of the reads files to get a report of the number of reads per sample and quality distribution across the reads. This generates a more basic output compared to FASTQC/MultiQC, but is sufficient for these purposes.
Note that we gave the output file above the extension .qzv since this a special type of artifact file - a visualization. You can look at the visualization by uploading the file to the QIIME2 view website and clicking on the Interactive Quality Plot tab at the top of the page
2.4. Trim primers and denoise
Choose one of these!
Either the Illumina or the PacBio trimming/denoising.
2.4.1. Illumina trim primers and denoise
2.4.1.1. Trim primers
Screen out reads that do not begin with primer sequence and remove primer sequence from reads using the cutadapt QIIME 2 plugin.
First, give your primer sequences. You can see a range of these available on the IMR website, but these should correspond to the primers used for sequencing.
16S “universal” V4-V5:
FWD="GTGYCAGCMGCCGCGGTAA"
REV="CCGYCAATTYMTTTRAGTTT"
16S bacterial V6-V8:
FWD="ACGCGHNRAACCTTACC"
REV="ACGGGCRGTGWGTRCAA"
16S archaeal V6-V8:
FWD="TYAATYGGANTCAACRCC"
REV="CRGTGWGTRCAAGGRGCA"
18S V4:
FWD="CYGCGGTAATTCCAGCTC"
REV="AYGGTATCTRATCRTCTTYG"
Fungal ITS2:
FWD="GTGAATCATCGAATCTTTGAA"
REV="TCCTCCGCTTATTGATATGC"
Once you have run one of these, run the command to trim the primers:
qiime cutadapt trim-paired \
   --i-demultiplexed-sequences reads_qza/reads.qza \
   --p-cores $NCORES \
   --p-front-f $FWD \
   --p-front-r $REV \
   --p-discard-untrimmed \
   --p-no-indels \
   --o-trimmed-sequences reads_qza/reads_trimmed.qza \
   --o-stats reads_qza/trim_stats.qza
If you received the error --p-cores option requires an argument make sure that you set the NCORES bash variable as described above.
2.4.1.2. Summarize trimmed FASTQs
Visualizing your output data is a good idea after any step to make sure nothing unexpected occurred. The following command generates a “visualization” file with the extension QZV. It is good to check that we still have most of our reads after trimming the primers! If you have very few or no reads left, this suggests that you got the primer sequence wrong in the above cutadapt command.
qiime demux summarize \
   --i-data reads_qza/reads_trimmed.qza \
   --o-visualization reads_qza/reads_trimmed_summary.qzv
2.4.1.3. Join paired-end reads
First, we will join the paired-end reads with VSEARCH:
qiime vsearch merge-pairs \
   --i-demultiplexed-seqs reads_qza/reads_trimmed.qza \
   --o-merged-sequences reads_qza/reads_trimmed_joined.qza \
   --o-unmerged-sequences reads_qza/reads_trimmed_unjoined.qza
Note that this command is more stringent than other approaches like PEAR when joining reads. If a low proportion of reads are joined at this step then one solution would be to export the data from QIIME2, run PEAR (see the run_pear.pl script that is part of this repository), and then re-import your data. In order to avoid those extra export/import manipulations, another solution is to restart from the raw reads, replacing the initial steps here until the Deblur/DADA2 step below - see our old instructions for Alternative Processing of Reads with PEAR.
2.4.1.4. Filter out low quality reads
This command will filter out low-quality reads based on the default options.
qiime quality-filter q-score \
   --i-demux reads_qza/reads_trimmed_joined.qza \
   --o-filter-stats filt_stats.qza \
   --o-filtered-sequences reads_qza/reads_trimmed_joined_filt.qza
It is a good idea at this point just to verify that there haven’t been any substantial losses of reads, before going through the whole ASV process, at either the joining or quality-filtering steps above:
qiime demux summarize \
   --i-data reads_qza/reads_trimmed_joined.qza \
   --o-visualization reads_qza/reads_trimmed_joined_filt_summary.qzv
2.4.1.4. Denoise with Deblur
Run the deblur workflow to correct reads and get amplicon sequence variants (ASVs). Note that the below command will retain singletons, which would have been filtered out unless we set --p-min-reads 1, and is for 16S sequences only. For other amplicon regions, you can either use the denoise-other option in the command and specify a reference database of sequences to use for positive filtering (as in the below versions for 18S and ITS) or use DADA2 as described below (the former still being preferred due to speed considerations).
Note that you will need to trim all sequences to the same length with the --p-trim-length option if you get an error. In order to determine the correct length to trim down to, take a look at the summary visualization generated above in order to select a length to trim back to that maintains the largest/acceptable quantity of reads.
We typically choose this length based on the Demultiplexed sequence length summary section of the Interactive Quality Plot tab in the reads_trimmed_joined_filt_summary.qzv file. In this summary, a subset of your sequences have been sampled to determine the lengths. This will look something like this:
| Total Sequences Sampled | 10000.0 |
|---|---|
| 2% | 366 nts |
| 9% | 368 nts |
| 25% | 370 nts |
| 50% (median) | 372 nts |
| 75% | 374 nts |
| 91% | 376 nts |
| 98% | 377 nts |
This means that 98% of my sequences (100% - 2%) are at least 366 nts long, 91% (100% - 9%) are at least 368 nts long, and so on. In this case, I would probably choose 366 as my cut-off because 366 still seems long enough that I can get reasonable taxonomic classification and it is within what is expected with my primer set, but I am removing any sequences that are very short. In some cases, you may want to do different things, for example, if you expect some off-target amplification that is much shorter than your amplicon target, you would want to trim to a length that would remove that off-target amplification. This can also be easier to choose for the 16S rRNA gene, where the length of the gene (and therefore the variable regions of the gene) is much more consistent than for e.g. 18S or ITS2.
Finally, input that length in the deblur option --p-trim-length below and run the command.
qiime deblur denoise-16S \
   --i-demultiplexed-seqs reads_qza/reads_trimmed_joined_filt.qza \
   --p-trim-length -1 \
   --p-sample-stats \
   --p-jobs-to-start $NCORES \
   --p-min-reads 1 \
   --output-dir deblur_output
When running 18S and ITS data with deblur you will need to specify custom reference files, which can be downloaded here.
For the 18S version (note the downloading and importing the database and only needs to be run once on your system):
wget https://kronos.pharmacology.dal.ca:8080/public_files/MH/deblur_non16S_ref/gb203_pr2_all_10_28_99p_clean_prob-rm.fasta

qiime tools import \
   --input-path gb203_pr2_all_10_28_99p_clean_prob-rm.fasta \
   --output-path gb203_pr2_all_10_28_99p_clean_prob-rm.qza \
   --type 'FeatureData[Sequence]'

qiime deblur denoise-other \
   --i-demultiplexed-seqs reads_qza/reads_trimmed_joined_filt.qza \
   --i-reference-seqs gb203_pr2_all_10_28_99p_clean_prob-rm.qza \
   --p-trim-length -1 \
   --p-sample-stats \
   --p-jobs-to-start $NCORES \
   --p-min-reads 1 \
   --output-dir deblur_output
For the ITS version (note the downloading and importing the database and only needs to be run once on your system):
wget https://kronos.pharmacology.dal.ca:8080/public_files/MH/deblur_non16S_ref/UNITE_sh_refs_qiime_ver8_99_s_all_02.02.2019.fasta

qiime tools import \
   --input-path UNITE_sh_refs_qiime_ver8_99_s_all_02.02.2019.fasta \
   --output-path UNITE_sh_refs_qiime_ver8_99_s_all_02.02.2019.qza \
   --type 'FeatureData[Sequence]'

qiime deblur denoise-other \
   --i-demultiplexed-seqs reads_qza/reads_trimmed_joined_filt.qza \
   --i-reference-seqs UNITE_sh_refs_qiime_ver8_99_s_all_02.02.2019.qza \
   --p-trim-length -1 \
   --p-sample-stats \
   --p-jobs-to-start $NCORES \
   --p-min-reads 1 \
   --output-dir deblur_output
2.4.1.5. Summarising Deblur output
Once a denoising pipeline has been run you can summarize the output table with the below command, which will create a visualization artifact for you to view.
qiime feature-table summarize \
    --i-table deblur_output/table.qza \
    --o-feature-frequencies deblur_output/deblur_table_summary_feature_frequencies.qza \
    --o-sample-frequencies deblur_output/deblur_table_summary_sample_frequencies.qza \
    --o-summary deblur_output/deblur_table_summary.qzv
We will use this visualization later to determine the the cut-offs for filtering the table below, but for now you should mainly take a look at the visualization to ensure that sufficient reads have been retained after running deblur. This denoising tool filters out reads that either do match to known noise or that do not match with low similarity to the expected amplicon region. If your samples have very low depth after running deblur (compared to the input read depth) this could be a red flag that either you ran the tool incorrectly, you have a lot of noise in your data, or that deblur is inappropriate for your dataset.
2.4.1.6. Copy denoised output to be same as from DADA2 below
So that the rest of the steps in the workflow can be identical regardless of whether you’ve used Deblur or DADA2, we’ll just copy the Deblur output.
mkdir denoised_output
cp deblur_output/*.qza denoised_output/
2.4.2. PacBio trim primers and denoise
At this stage, the main 2 pipelines you can use are based on either deblur or DADA2. We recommend running DADA2, which now supports PacBio reads, as Deblur may not work correctly since it does not currently have a PacBio mode.
2.4.2.1. Run DADA2
Run the DADA2 workflow to remove primers, correct reads and get amplicon sequence variants (ASVs). Note that the previous version of the PacBio CCS Amplicon SOP included two steps (“Resolve orientation problems” and “Trim primers with cutadapt”) prior to running DADA2. Those steps are now included as part of DADA2’s “denoise-ccs” mode described below. Also, note that we are not doing any form of initial quality filtering (unlike our Illumina SOP) or truncation in the below command due to the fact the CCS reads are already of very high quality when produced (HiFi reads are 99% consensus accuracy). You will probably also want to increase the number of threads used below to the maximum your system has available. If your PacBio data is not CCS in nature or you have used a lower consensus threshold (ie: <99%), then we would suggest you add in a quality-filter step.
First, give your primer sequences. You can see a range of these available on the IMR website, but these should correspond to the primers used for sequencing.
16S bacteria-specific:
FWD="AGRGTTYGATYMTGGCTCAG"
REV="RGYTACCTTGTTACGACTT"
16S archaea-specific:
FWD="TCCGGTTGATCCYGCCGG"
REV="CRGTGWGTRCAAGGRGCA"
18S eukaryote-specific:
FWD="CTGGTTGATYCTGCCAGT"
REV="TGATCCTTCTGCAGGTTCACCTAC"
ITS eukaryote-specific:
FWD="TAGAGGAAGTAAAAGTCGTAA"
REV="TCCTCCGCTTWTTGWTWTGC"
mkdir dada2_output

qiime dada2 denoise-ccs \
   --i-demultiplexed-seqs reads_qza/reads.qza \
   --p-min-len 1200 --p-max-len 1800 \
   --p-max-ee 18 \
   --p-pooling-method pseudo \
   --p-n-reads-learn 100000 \
   --p-front $FWD --p-adapter $REV \
   --p-n-threads $NCORES \
   --o-table dada2_output/table.qza \
   --o-representative-sequences dada2_output/representative_sequences.qza \
   --o-denoising-stats dada2_output/stats.qza \
   --o-base-transition-stats dada2_output/base_transition_stats.qza \
   --verbose
Note we are using linked anchored adapters here to ensure only reads having the primers at the extremities are retained and a size-range of 1200-1800 nt for both 16S primer sets to allow some indels (there should be relatively few in actuality), but prevent amplicon dimers (we’ve observed ~1% in PacBio CCS data) from passing through, since the size of the 16S amplicon here is ~1500 nt.
If you are using the 18S primer sets, you should change a couple of the parameters:
   --p-min-len 1000 --p-max-len 3000 \
   --p-max-ee 30 \
There is a much wider size-range, around the ~1800 nt normal size, due to the fact some species of Eukaryotes have much larger indels in their rRNA than Bacteria do.
If using the ITS primer set, you should also change a couple of the parameters:
   --p-min-len 300 --p-max-len 900 \
   --p-max-ee 9 \
Again, size-range is modified for the proper range to keep variation, but hopefully remove larger dimers; ~600 nt average size.
2.4.2.2. Run DADA2
Once a denoising pipeline has been run you can summarize the output table with the below command, which will create a visualization artifact for you to view.
qiime feature-table summarize \
    --i-table dada2_output/table.qza \
    --o-feature-frequencies dada2_output/dada2_table_summary_feature_frequencies.qza \
    --o-sample-frequencies dada2_output/dada2_table_summary_sample_frequencies.qza \
    --o-summary dada2_output/dada2_table_summary.qzv
We will use this visualization later to determine the the cut-offs for filtering the table below, but for now you should mainly take a look at the visualization to ensure that sufficient reads have been retained after running DADA2.
If you see substantial losses of read numbers after this step, then make absolutely certain you are using the correct primer sequences (in the correct linked orientations) and have not filtered out most of your reads due to the size-range restrictions - this would indicate a problem in matching your fragment with the correct parameters (especially important if using custom primers and adjusting all the above values).
2.4.2.3. Copy denoised output to be same as from Deblur
So that the rest of the steps in the workflow can be identical regardless of whether you’ve used Deblur or DADA2, we’ll just copy the Deblur output.
mkdir denoised_output
cp dada2_output/*.qza denoised_output/
3. Assign taxonomy to ASVs
You can assign taxonomy to your ASVs using a Naive-Bayes approach implemented in the scikit learn Python library and one of many databases. We have provided details on downloading these classifiers for several common databases as well as for building your own. Some databases that we have used:
- SILVA (16S/18S SSU)
- Greengenes 2 (16S)
- UNITE (ITS, fungi and other eukaryotes)
- PR2 (18S, Protist Ribosomal Reference)
- HOMD (16S, Human Oral Microbiome Database)
- GTDB (16S, Genome Taxonomy DataBase)
- MitoFish (12S)
3.1. Build or acquire taxonomic classifier
Choose one of these!
Either download a taxonomic classifier from somewhere or build one yourself.
This approach requires that a classifier be trained in advance on a reference database. We recommend users use a widely used classifier to help ensure there are no unexpected issues with the Naive-Bayes model. We previously maintained primer-specific classifiers, which theoretically can provide more accurate classifications, but we no longer do this due to concerns regarding issues with the trained models that are difficult to catch if only a couple people are running them. No matter what approach you use, it’s a good idea to run a few sanity checks on the output to make sure it worked correctly for your data (see below).
You can see the available downloads on the QIIME 2 resources page. The SciKit-Learn Naive Bayes classifiers will typically work across multiple QIIME 2 versions - the important thing is the database that they are trained on and the SciKit Learn version that they use.
QIIME 2 2026.7 used sklearn version 1.7.1.
3.1.1. Download a taxonomic classifier
SILVA v144:
wget https://www.arb-silva.de/fileadmin/silva_databases/current/QIIME2/2026.7/SSU/full-length/uniform/SILVA_144_SSURef_NR99_full-length_prokaryotes_rank-propagation_uniq_genus_uniform_classifier.qza
Note that SILVA now only provides taxonomic classifications down to the genus level. This may not be a problem if you have a short variable region where you don’t expect many species-level classifications, but could be problematic if you have full-length reads and are expecting to be able to classify many sequences to the species-level.
GTDB r232:
wget https://zenodo.org/records/21619532/files/gtdb-r232.0-2026.7.0-classifier.qza?download=1 -O gtdb-r232.0-2026.7.0-classifier.qza
We also keep some additional classifiers on our lab server here.
3.1.2. Build a taxonomic classifier
How easy this is to do will likely depend on how nicely formatted the taxonomy files are already. To do this, you will need:
- A fasta file containing the representative sequences
- A header-less tab-delimited file with two columns: one with sequence ID’s and the second with semi-colon separated taxonomy
(These could already be imported into QIIME 2 .qza files)
This is an example for making a Human Oral Mirobiome Database (HOMD) classifier.
Make a folder to work from:
mkdir q2_classifier_homd
cd q2_classifier_homd
Download the relevant files from the HOMD FTP:
wget https://www.homd.org//ftp/16S_rRNA_refseq/HOMD_16S_rRNA_RefSeq/V16.03/HOMD_16S_rRNA_RefSeq_V16.03_full.fasta
wget https://www.homd.org//ftp/16S_rRNA_refseq/HOMD_16S_rRNA_RefSeq/V16.03/HOMD_16S_rRNA_RefSeq_V16.03.qiime.taxonomy
These look like:
head -2 HOMD_16S_rRNA_RefSeq_V16.03_full.fasta
>HMT-748_16S000001 HMT-748 Campylobacter rectus
GAGTTTGATCCTGGCTCAGAGTGAACGCTGGCGGCGTGCCTAATACATGCAAGTCGAACGGAGATTAAGTAGCTTGCTATTTAATCTTAGTGGCGCACGGGTGAGTAATATATAGCTAATCTGCCCTACACTAGAGGACAACAGTTGGAAACGACTGCTAATACTCTATACTCCTTCTAAGCATAAGCTTAGTCGGGAAAGTTAATAAAATTTGCTTTTTGGTTTCATCTTGAGAGATATGGACGTATAACAACTAAATTGATACGCCGATGTGGCAAACATCGGTGTGCTTTAGGTGGGTCAAGGGAGCGCTTGCGCTTCTTGTCGCAAAGAAAGGCTTTGCCTTTCTGCGAAGTCCGTATTTGTCAAGATGAAATCTTGCAAATGTATTTTTTCGGTGTAGGATGAGGCTATATCGTATCAGCTAGTTGGTGAGGTAATGGCTCACCAAGGCTATGACGCGTAACTGGTCTGAGAGGATGATCAGTCACACTGGAACTGAGACACGGTCCAGACTCCTACGGGAGGCAGCAGTAGGGAATATTGCTCAATGGGGGAAACCCTGAAGCAGCAACGCCGCGTGGAGGATGACACTTTTCGGAGCGTAAACTCCTTTTCTTGGGAAAGAATTATGACGGTACCCAAGGAATAAGCACCGGCTAACTCCGTGCCAGCAGCCGCGGTAATACGGAGGGTGCAAGCGTTACTCGGAATCACTGGGCGTAAAGGACGCGTAGGCGGATTATCAAGTCTCTTGTGAAATCTAACGGCTTAACCGTTAAACTGCTTGGGAAACTGATAATCTAGAGTAAGGGAGAGGCAGATGGAATTCTTGGTGTAGGGGTAAAATCCGTAGAGATCAAGAAGAATACCCATTGCGAAAGCGATCTGCTGGAACTTAACTGACGCTAATGCGTGAAAGCGTGGGGAGCAAACAGGATTAGATACCCTGGTAGTCCACGCCCTAAACGATGTATACTAGTTGTTGCTTCGCTAGTCGAGGCAGTAATGCACCTAACGGATTAAGTATACCGCCTGGGGAGTACGGTCGCAAGATTAAAACTCAAAGGAATAGACGGGGACCCGCACAAGCGGTGGAGCATGTGGTTTAATTCGAAGATACGCGAAGAACCTTACCCGGACTTGATATCTAACAAATCATCCAGAGATGGAAGAGTGTCTGCTTGCAGAAATGTTAAGACAGGTGCTGCACGGCTGTCGTCAGCTCGTGTCGTGAGATGTTGGGTTAAGTCCCGCAACGAGCGCAACCCACGTCATTAGTTGCTAACGGTTCGGCCGAGCACTCTAATGAGACTGCCTTCGTAAGGAGGAGGAAGGTGTGGACGACGTCAAGTCATCATGGCCCTTATGTCCGGGGCGACACACGTGCTACAATGGCGTATACAATGAGACGCAATATCGCGAGATGGAGCAAATCTATAAAATACGTCCCAGTTCGGATTGGAGTCTGCAACTCGACTCCATGAAGCCGGAATCGCTAGTAATCGTAGATCAGCCATGCTACGGTGAATACGTTCCCGGGTCTTGTACTCACCGCCCGTCACACCATGGGAGTTGATTTCACTCGAAGCCCAAATACCAAACCGGTTATGGTCCACAGTGGAATCAGCGACTGGGGTGAAGTCGTAACAAGGTAACCGTAGGAGAACCTGCG

head -5 HOMD_16S_rRNA_RefSeq_V16.03.qiime.taxonomy
HMT-748_16S000001	k__Bacteria;p__Pseudomonadota;c__Epsilonproteobacteria;o__Campylobacterales;f__Campylobacteraceae;g__Campylobacter;s__rectus
HMT-580_16S000002	k__Bacteria;p__Pseudomonadota;c__Epsilonproteobacteria;o__Campylobacterales;f__Campylobacteraceae;g__Campylobacter;s__curvus
HMT-151_16S000003	k__Bacteria;p__Bacillota;c__Negativicutes;o__Selenomonadales;f__Selenomonadaceae;g__Selenomonas;s__sputigena
HMT-684_16S000004	k__Bacteria;p__Bacillota;c__Negativicutes;o__Selenomonadales;f__Selenomonadaceae;g__Mitsuokella;s__multacida
HMT-580_16S000005	k__Bacteria;p__Pseudomonadota;c__Epsilonproteobacteria;o__Campylobacterales;f__Campylobacteraceae;g__Campylobacter;s__curvus
Import them into QIIME2:
qiime tools import --type 'FeatureData[Sequence]' \
    --input-path HOMD_16S_rRNA_RefSeq_V16.03_full.fasta \
    --output-path HOMD_16S_rRNA_RefSeq_V16.03_seqs.qza

qiime tools import --type 'FeatureData[Taxonomy]' --input-format HeaderlessTSVTaxonomyFormat \
    --input-path HOMD_16S_rRNA_RefSeq_V16.03.qiime.taxonomy \
    --output-path HOMD_16S_rRNA_RefSeq_V16.03_tax.qza
Build/train the classifier:
qiime feature-classifier fit-classifier-naive-bayes \
  --i-reference-reads HOMD_16S_rRNA_RefSeq_V16.03_seqs.qza \
  --i-reference-taxonomy HOMD_16S_rRNA_RefSeq_V16.03_tax.qza \
  --o-classifier HOMD_16S_rRNA_RefSeq_V16.03.qza
This is an example for the Greengenes2 database.
Make a folder to work from:
mkdir q2_classifier_gg2
cd q2_classifier_gg2
Download the relevant files from their FTP site:
wget http://ftp.microbio.me/greengenes_release/2024.09/2024.09.seqs.fna.qza
wget http://ftp.microbio.me/greengenes_release/2024.09/2024.09.taxonomy.asv.tsv.qza

mv 2024.09.seqs.fna.qza greengenes2_2024.09.seqs.fna.qza
mv 2024.09.taxonomy.asv.tsv.qza greengenes2_2024.09.taxonomy.asv.tsv.qza
Build/train the classifier:
qiime feature-classifier fit-classifier-naive-bayes \
  --i-reference-reads greengenes2_2024.09.seqs.fna.qza \
  --i-reference-taxonomy greengenes2_2024.09.taxonomy.asv.tsv.qza \
  --o-classifier greengenes2_2024.09.qza
3.2. Run taxonomic classification
Provide the path to your chosen classifier, for example:
CLASSIFIER=/home/shared/MH2/sklearn_classifiers/sklearn_1.7.1/gtdb-r232.0-2026.7.0-classifier.qza
You will need to modify this command for yourself!!
You can run the taxonomic classification with this command, which is one of the longest running and most memory-intensive command of the SOP:
qiime feature-classifier classify-sklearn \
   --i-reads denoised_output/representative_sequences.qza \
   --i-classifier $CLASSIFIER \
   --p-read-orientation same \
   --p-n-jobs $NCORES \
   --output-dir taxa
If you receive an error related to insufficient memory (and if you cannot increase your memory usage) then you can look into the --p-reads-per-batch option and set this to be lower than the default (which is dynamic depending on sample depth and the number of threads) and also try running the command with fewer jobs (e.g. set --p-n-jobs 1)
As with all QZA files, you can export the output file to take a look at the classifications and confidence scores - this needs to be done in this case, as we use the exported taxonomy.tsv file later on when exporting all the final analysis files:
qiime tools export \
   --input-path taxa/classification.qza \
   --output-path taxa
3.3. Assess a subset of taxonomic assignments with BLAST
The performance of the taxonomic classification is difficult to assess without a gold-standard reference, but nonetheless one basic sanity check is to compare the taxonomic assignments with the top BLASTn hits for certain ASVs.
It is simple to do this with QIIME 2 by running:
qiime feature-table tabulate-seqs --i-data denoised_output/representative_sequences.qza \
                                  --o-visualization denoised_output/representative_sequences.qzv
The file denoised_output/representative_sequences.qzv is a QIIME 2 visualization file that you can open in the QIIME 2 viewer. The format makes it easy to BLAST certain ASVs against the NCBI nt database (just click on each of the sequences!). By comparing these BLAST hits with the taxonomic assignment of ASVs generated above you can reassure yourself that the taxonomic assignments overall worked correctly. It’s a good idea to select ~5 ASVs to BLAST for this validation, which should be from taxonomically different groups, such as different phyla, according to the taxonomic classifier.
You can then check the taxonomy that was assigned to them using your classifier - you can either open up the taxonomy.tsv file and search for the Feature ID/ASV names there, or you can use the grep command like so:
grep "e662c4255904d5745ec8ed3db822c549" taxa/taxonomy.tsv
4. Filtering resultant table
Filtering the denoised table is an important step of microbiome data analysis. You can see more details on this process in the QIIME 2 filtering tutorial.
4.1. Filter out rare ASVs
Based on the summary visualization created in the denoising steps above you can choose a cut-off for how frequent a variant needs to be (and optionally how many samples need to have the variant) for it to be retained. One possible choice would be to remove all ASVs that have a frequency of less than 0.1% of the mean sample depth. This cut-off excludes ASVs that are likely due to MiSeq bleed-through between runs (reported by Illumina to be 0.1% of reads). Although advances in Illumina technology mean that this may no longer be the case (and this also may vary for PacBio), this is still what we tend to use.
To calculate this cut-off you would identify the mean sample depth in the visualization created above (deblur_output/deblur_table_summary.qzv or dada2_output/dada2_table_summary.qzv), multiply it by 0.001, and round to the nearest integer.
Note that there are several different names that you’ll see used for sample depth! This refers to the number of reads/sequences in each sample, and in the QIIME2 visualisation, you are looking for the “Mean frequency” in the “Frequency per sample” section.
Once you’ve determined how you would like to filter your table you can do so with this command (X is a placeholder for your choice):
qiime feature-table filter-features \
   --i-table denoised_output/table.qza \
   --p-min-frequency X \
   --p-min-samples 1 \
   --o-filtered-table denoised_output/table_filt.qza
4.2. Filter out contaminant and unclassified ASVs
Now that we have assigned taxonomy to our ASVs we can use that information to remove ASVs which are likely contaminants or noise based on the taxonomic labels. Two common contaminants in 16S sequencing data are mitochondrial and chloroplast 16S sequences, which can be removed by excluding any ASV which contains those terms in its taxonomic label. It can also be sometimes useful to exclude any ASV that is unclassified at the phylum level since these sequences could be noise (e.g. possible chimeric sequences). Note that if your data has not been classified against the default database you may need to change p__ to be a string that enables phylum-level assignments to be identified or simply omit that line.
In general though, it can be very informative if your sequencing reads are coming back with significant amounts of unclassified ASVs as it can indicate upstream analysis problems or indicate you are studying a poorly characterized environment where you have a good chance of identifying a lot of novel phyla. Therefore, our recommendation is to not filter out the unclassified sequences by default:
qiime taxa filter-table \
   --i-table denoised_output/table_filt.qza \
   --i-taxonomy taxa/classification.qza \
   --p-exclude mitochondria,chloroplast \
   --o-filtered-table denoised_output/table_filt_contam.qza
If you aren’t trying to remove groups like this (if you have sequenced a different marker gene, for example), then you could just skip this step. Keep in mind that you may also need to modify the file names given to the following commands.
If you do want to exclude all the unclassifieds, then run the following instead (with the above caveat that the --p-include line might need to be adapted according to the tax database used - this just means that we only want to keep ASVs that have at least a phylum-level classification):
qiime taxa filter-table \
   --i-table denoised_output/table_filt.qza \
   --i-taxonomy taxa/classification.qza \
   --p-include p__ \
   --p-exclude mitochondria,chloroplast \
   --o-filtered-table denoised_output/table_filt_contam.qza
4.3. Exclude low-depth samples
This is optional!
We often investigate several different cut-offs in our downstream analysis and wait until then. If you skip this here, remember that it is important to check that you don’t have any very low depth samples remaining in your analysis!
Often certain samples will have quite low depth after these filtering steps, which can be excluded from downstream analyses since they will largely add noise. There is no single cut-off that works best for all datasets, but researchers often use minimum cut-offs within the range of 1000 to 4000 reads. You can also use a cut-off much lower than this if you want to retain all samples except those that failed entirely (e.g. depth < 50 reads). Ideally you would choose this cut-off after visualizing rarefaction curves to determine at what read depth the richness of your samples plateaus and choose a cut-off as close to this plateau as possible while retaining sufficient sample size for your analyses.
To perform this rarefaction curve analysis you would first need to summarize the filtered table we produced in the last step:
qiime feature-table summarize \
    --i-table denoised_output/table_filt_contam.qza \
    --o-feature-frequencies denoised_output/table_filt_contam_summary_feature_frequencies.qza \
    --o-sample-frequencies denoised_output/table_filt_contam_summary_sample_frequencies.qza \
    --o-summary denoised_output/table_filt_contam_summary.qzv
From this table you need to determine the maximum depth across your samples. You can then generate the rarefaction curves with this command (where X is a placeholder for the max depth across samples).
qiime diversity alpha-rarefaction \
   --i-table denoised_output/table_filt_contam.qza \
   --p-max-depth X \
   --p-steps 20 \
   --p-metrics 'observed_features' \
   --o-visualization rarefaction_curves_test.qzv
Note that if you just copy and paste the number from your maximum sample depth/frequency and get an error, it is likely because QIIME doesn’t want there to be a comma. So instead of e.g.
57,848, this should be57848.
If the depth of your samples varies quite a lot, then you may find that the --p-max-depth is too large to easily see your samples with lower read depths. In this case, I would recommend choosing a lower number (e.g. 10000) and re-running this step with that number.
Take a look at these curves to help decide on a minimum depth cut-off for retaining samples. Once you decide on a hard cut-off you can exclude samples below this cut-off with this command (where SET_CUTOFF is a placeholder for the minimum depth you select):
qiime feature-table filter-samples \
   --i-table denoised_output/table_filt_contam.qza \
   --p-min-frequency SET_CUTOFF \
   --o-filtered-table denoised_output/table_final.qza
In many analyses, we might not want to exclude samples at this point. Sometime we will investigate using a few different cut-offs to see how much these lower depth samples impact our results (if at all), or we might just be running a pilot study so we may be less concerned with whether we have kept (potentially) lower quality samples.
If you do not wish to exclude any samples, then you can simply make a copy of the QZA file with the final table filename (i.e.
cp denoised_output/table_filt_contam.qza denoised_output/table_final.qza), since this is the filename used for the remaining commands below.
4.4. Subset and summarize filtered table
Once we have our final filtered table we will need to subset the QZA of ASV sequences to the same set. You can exclude the low frequency ASVs from the sequence file with this command:
qiime feature-table filter-seqs \
   --i-data denoised_output/representative_sequences.qza \
   --i-table denoised_output/table_final.qza \
   --o-filtered-data denoised_output/rep_seqs_final.qza
Finally, you can make a new summary of the final filtered abundance table:
qiime feature-table summarize \
    --i-table denoised_output/table_final.qza \
    --o-feature-frequencies denoised_output/table_final_summary_feature_frequencies.qza \
    --o-sample-frequencies denoised_output/table_final_summary_sample_frequencies.qza \
    --o-summary denoised_output/table_final_summary.qzv
5. Build/insert sequences into phylogenetic tree
Choose one of these!
Either insert your sequences into an existing tree (recommended for 16S) or build a new tree.
Note that if you will be running PICRUSt2-v2.6.4 (optional step 6 below) then this includes inserting sequences into GTDB r214 bacterial and archaeal reference trees. These are provided as a standard output of the pipeline and may be used instead of this insertion step. The main benefit to carrying out this insertion step (section 5.1) instead is that - depending on the reference/database used - it may provide a combined tree.
We recommend using insertion into an existing tree for 16S amplicons, but the easiest approach for 18S and ITS data is to instead create a de novo tree as outlined below.
5.1. Insertion into existing tree with SEPP
SEPP is one method for placing short sequences into a reference phylogenetic tree. This is a useful way of determining a phylogenetic tree for your ASVs, particularly as short amplicons do not typically make robust trees. As with the taxonomic classifiers, there are several that could be used.
You don’t need to use the same database for this as you used for taxonomic classification - what really matters here is that the tree is constructed with a relatively complete set of taxa. It will essentially be used as a skeleton for creating the tree of your study sequences.
We have typically used the Greengenes 2 (2022.10) SEPP reference, which is available on their FTP site here:
wget https://ftp.microbio.me/greengenes_release/2022.10/2022.10.backbone.sepp-reference.qza
There is also a SILVA version available here:
wget https://data.qiime2.org/classifiers/sepp-ref-dbs/sepp-refs-silva-128.qza
Now we can do the fragment insertion:
qiime fragment-insertion sepp \
   --i-representative-sequences denoised_output/rep_seqs_final.qza \
   --i-reference-database reference_tree.qza \
   --o-tree asvs-tree.qza \
   --o-placements insertion-placements.qza \
   --p-threads $NCORES
Where reference_tree.qza should be replaced with whichever tree you downloaded above.
Note that we have seen some issues with SEPP where it uses all available threads on a server. Running it with this additional command will limit it: taskset -c 0-23 (in this case, it is limited to 24 threads).
You could run the above command with this like so:
taskset -c 0-23 qiime fragment-insertion sepp \
                  --i-representative-sequences denoised_output/rep_seqs_final.qza \
                  --i-reference-database reference_tree.qza \
                  --o-tree asvs-tree.qza \
                  --o-placements insertion-placements.qza \
                  --p-threads $NCORES
5.2. Building a tree
Given the lack of a pre-calculated reference tree for 18S and ITS data (unlike the above 16S tree) to do direct placement, we create the tree de novo here below.
5.2.1. Making multiple-sequence alignment
We’ll need to make a multiple-sequence alignment of the ASVs before running FastTree. First, we’ll make a folder for the output files.
mkdir tree_out
We’ll use MAFFT to make a de novo multiple-sequence alignment of the ASVs.
qiime alignment mafft --i-sequences denoised_output/rep_seqs_final.qza \
                      --p-n-threads $NCORES \
                      --o-alignment tree_out/rep_seqs_final_aligned.qza
5.2.2. Filtering multiple-sequence alignment
Variable positions in the alignment need to be masked before FastTree is run, which can be done with this command:
qiime alignment mask --i-alignment tree_out/rep_seqs_final_aligned.qza \
                     --o-masked-alignment tree_out/rep_seqs_final_aligned_masked.qza
5.2.3. Running FastTree
Finally FastTree can be run on this masked multiple-sequence alignment:
qiime phylogeny fasttree --i-alignment tree_out/rep_seqs_final_aligned_masked.qza \
                         --p-n-threads $NCORES \
                         --o-tree tree_out/rep_seqs_final_aligned_masked_tree.qza
5.2.4. Add root to tree
FastTree returns an unrooted tree. One basic way to add a root to a tree is to add it add it at the midpoint of the largest tip-to-tip distance in the tree, which is done with this command:
qiime phylogeny midpoint-root --i-tree tree_out/rep_seqs_final_aligned_masked_tree.qza \
                              --o-rooted-tree tree_out/rep_seqs_final_aligned_masked_tree_rooted.qza
5.2.5. Re-name file
To keep this output filename consistent with the SOP you can simply make a copy of this output tree.
cp tree_out/rep_seqs_final_aligned_masked_tree_rooted.qza asvs-tree.qza
6. Functional prediction with PICRUSt2
This is optional!
PICRUSt2 is a tool for the prediction of metagenome functions using amplicon data. It is a tool that has been developed and maintained within our lab. It has some well-documented limitations and the results obtained from it should only ever be used for predictive purposes and generating hypotheses, but it can be useful. While the stand-alone tool includes more options for running, we have also developed an implementation of it within QIIME 2 (the most recent version at the time of writing is for QIIME2 2026.7 and PICRUSt2-v2.6.4).
And then run it:
qiime picrust2 full-pipeline \
   --i-table denoised_output/table_final.qza \
   --i-seq denoised_output/rep_seqs_final.qza \
   --output-dir q2-picrust2_output \
   --p-threads $NCORES \
   --verbose
You can see more details about running PICRUSt2 within QIIME2 here.
I would then take a look at the NSTI file to see which domain your sequences were placed in:
qiime tools export \
   --input-path q2-picrust2_output/combined_nsti.qza \
   --output-path q2-picrust2_output/nsti_exported

less q2-picrust2_output/nsti_exported/metadata.tsv
If I wanted to use the trees created by PICRUSt2 for downstream analysis, it would be useful to check how many of my ASVs were placed into each tree:
grep -c "arc" q2-picrust2_output/nsti_exported/metadata.tsv
grep -c "bac" q2-picrust2_output/nsti_exported/metadata.tsv
7. Basic statistics and visualisation within QIIME2
This is optional!
We’d recommend doing something in R/Python - or as described in our downstream analysis - but if you’d like a quick overview of your results then this is nice :)
7.1. Format metadata file
You can format the metadata file (which is in a compatible format to the QIIME 1 mapping files) in a spreadsheet as described on the QIIME 2 website. The only required column is the sample id column, which should be first (and can have one of several names). All other columns should correspond to sample metadata.
This can be done like so (for example if your file is called metadata.txt and is found in the folder /home/user):
METADATA="/home/user/project_name/metadata.txt"
If you are using the tutorial data that we have provided and you imported it using the manifest file, you will need to make a new metadata file that has the column names that QIIME2 is expecting, in the right place:
cut -f2- arctic_study_metadata_pacbio.txt > arctic_study_metadata_q2_formatted.txt
sed -i 's/sample_rename/sampleid/g' arctic_study_metadata_q2_formatted.txt
If you didn’t import it using the manifest file, you will just need to rename the first column:
sed -i 's/Run/sampleid/g' arctic_study_metadata_illumina.txt
For either of these, there is also a column name in this file that will cause an error with the QIIME 2 plugins, and you can modify that like so:
sed -i '1s#country_and/or_sea#country_and_or_sea#' arctic_study_metadata_illumina.txt
sed -i '1s#country_and/or_sea#country_and_or_sea#' arctic_study_metadata_q2_formatted.txt
And some of the values (namely switching any occurrences of / to - (otherwise these get misinterpreted as different folders):
awk 'BEGIN{FS=OFS="\t"}
     NR==1{for(i=1;i<=NF;i++) if($i=="Collection_Date") c=i; print; next}
     {gsub("/","-",$c); print}' arctic_study_metadata_illumina.txt > arctic_study_metadata_illumina_fixed.txt

awk 'BEGIN{FS=OFS="\t"}
     NR==1{for(i=1;i<=NF;i++) if($i=="Collection_Date") c=i; print; next}
     {gsub("/","-",$c); print}' arctic_study_metadata_q2_formatted.txt > arctic_study_metadata_q2_formatted_fixed.txt
And then rewrite the file path above appropriately for whichever file you end up with.
7.2. Generate rarefaction curves
A key quality control step is to plot rarefaction curves for all of your samples to determine if you performed sufficient sequencing. The below command will generate these plots (make sure you have the correct maximum sequencing depth to replace X with as per your filtered feature table, denoised_output/table_final_summary.qzv above).
qiime diversity alpha-rarefaction \
  --i-table denoised_output/table_final.qza \
  --p-max-depth X \
  --p-steps 20 \
  --m-metadata-file $METADATA \
  --i-phylogeny asvs-tree.qza \
  --o-visualization rarefaction_curves.qzv
7.3. Calculating diversity metrics and generating ordination plots
Common alpha and beta-diversity metrics can be calculated with a single command in QIIME 2. Ordination plots (such as PCoA plots for weighted UniFrac distances) will be generated automatically as well. This command will also rarefy all samples to the sample sequencing depth before calculating these metrics (X is a placeholder for the lowest reasonable sample depth; samples with depth below this cut-off will be excluded).
qiime diversity core-metrics-phylogenetic \
  --i-table denoised_output/table_final.qza \
  --i-phylogeny asvs-tree.qza \
  --p-sampling-depth X  \
  --m-metadata-file $METADATA \
  --p-n-jobs-or-threads $NCORES \
  --output-dir diversity
For alpha diversity visualizations, you will need to produce boxplots comparing the different categories in your metadata file. For example, to create boxplots comparing the Shannon alpha-diversity metric you can use this command:
qiime diversity alpha-group-significance \
  --i-alpha-diversity diversity/shannon_vector.qza \
  --m-metadata-file $METADATA \
  --o-visualization diversity/shannon_compare_groups.qzv
You will need to change this command for the other alpha diversity metrics. You can see the other metrics available by running
ls diversity/*_vector.qza.
Note that you can also export this or any other diversity metric file (ending in .qza) as you have done previously and analyze them with a different program.
If you want to run a PERMANOVA test to calculate differences in beta diversity between groups of interest, you can run the following command. Remember you will need to change it according to which beta diversity metric you are using, and you will also have to specify your metadata category of interest.
qiime diversity beta-group-significance \
  --i-distance-matrix diversity/bray_curtis_distance_matrix.qza \
  --m-metadata-file $METADATA \
  --m-metadata-column METADATA_CATEGORY \
  --o-visualization diversity/bray_curtis_compare_groups.qzv
7.4. Generate stacked bar chart of taxa relative abundances
Another useful output is the interactive stacked bar-charts of the taxonomic abundances across samples, which can be output with this command:
qiime taxa barplot \
  --i-table denoised_output/table_final.qza \
  --i-taxonomy taxa/classification.qza \
  --m-metadata-file $METADATA \
  --o-visualization taxa/taxa_barplot.qzv
7.5. Identifying differentially abundant features with ANCOM
ANCOM is one method to test for differences in the relative abundance of features between sample groupings. It is a compositional approach that makes no assumptions about feature distributions. However, it requires that all features have non-zero abundances so a pseudocount first needs to be added (1 is a typical pseudocount choice):
qiime composition add-pseudocount \
  --i-table denoised_output/table_final.qza \
  --p-pseudocount 1 \
  --o-composition-table denoised_output/table_final_pseudocount.qza
Then ANCOM can be run with this command; note that CATEGORY is a placeholder for the text label of your category of interest from the metadata file.
qiime composition ancom \
  --i-table denoised_output/table_final_pseudocount.qza \
  --m-metadata-file $METADATA \
  --m-metadata-column METADATA_CATEGORY \
  --output-dir ancom_output
7.6. Phylogenetic Robust Aitchison PCA
New approaches to calculating beta diversity are still being invented. For example, Phylogenetic Robust Aitchison PCA (RPCA) aims to account for both the compositional and phyogenetic nature of microbiome data can be run using the gemelli toolbox.
We have been using the Phylogenetic RPCA method in a lot of our latest studies. We have often applied this after removing low abundance features from our samples, but if you would like to use it then you can see the commands below, and you can also use this to remove low abundance features. I will also note that we typically find that if there are large biological differences/effect sizes between our sample groupings, we tend to pick them up with any of the beta diversity metrics. However, we do like that this one both accounts for compositionality and incorporates phylogeny.
And then you can run it:
mkdir phylo_rpca
qiime gemelli phylogenetic-rpca-with-taxonomy \
    --i-table denoised_output/table_final.qza \
    --i-phylogeny asvs-tree.qza \
    --m-taxonomy-file taxa/classification.qza \
    --p-min-feature-count 0 \
    --p-min-sample-count 0 \
    --o-biplot phylo_rpca/phylo-ordination.qza \
    --o-distance-matrix phylo_rpca/phylo-distance.qza \
    --o-counts-by-node-tree phylo_rpca/phylo-tree.qza \
    --o-counts-by-node phylo_rpca/phylo-table.qza \
    --o-t2t-taxonomy phylo_rpca/phylo-taxonomy.qza
View the biplot as an emperor visualisation:
qiime emperor biplot \
    --i-biplot phylo_rpca/phylo-ordination.qza \
    --m-sample-metadata-file $METADATA \
    --o-visualization phylo_rpca/emperor-biplot.qzv
And export the ordination results and distance matrix:
qiime tools export \
  --input-path phylo_rpca/phylo-ordination.qza \
  --output-path phylo_rpca

qiime tools export \
  --input-path phylo_rpca/phylo-distance.qza \
  --output-path phylo_rpca
8. Exporting the final files
Lastly, to get the BIOM file (with associated taxonomy) and FASTA file (one per ASV) for your dataset to plug into other programs you can use the commands below.
8.1. Export the fasta file of your ASVs
To export the FASTA:
qiime tools export \
   --input-path denoised_output/rep_seqs_final.qza \
   --output-path denoised_output_exported
8.2. Export your feature table
To export the BIOM table (with taxonomy added as metadata):
sed -i -e '1 s/Feature/#Feature/' -e '1 s/Taxon/taxonomy/' taxa/taxonomy.tsv

qiime tools export \
   --input-path denoised_output/table_final.qza \
   --output-path denoised_output_exported

biom add-metadata \
   -i denoised_output_exported/feature-table.biom \
   -o denoised_output_exported/feature-table_w_tax.biom \
   --observation-metadata-fp taxa/taxonomy.tsv \
   --sc-separated taxonomy

biom convert \
   -i denoised_output_exported/feature-table_w_tax.biom \
   -o denoised_output_exported/feature-table_w_tax.txt \
   --to-tsv \
   --header-key taxonomy
8.3. Export your phylogenetic tree
To export the tree of your ASVs:
qiime tools export \
  --input-path asvs-tree.qza \
  --output-path denoised_output_exported
8.4. Export the PICRUSt2 output
First, export the pathways:
qiime tools export \
   --input-path q2-picrust2_output/pathway_abundance.qza \
   --output-path q2-picrust2_output/pathabun_exported

biom convert \
   -i q2-picrust2_output/pathabun_exported/feature-table.biom \
   -o q2-picrust2_output/pathabun_exported/feature-table.tsv \
   --to-tsv
Then the KOs:
qiime tools export \
   --input-path q2-picrust2_output/ko_metagenome.qza \
   --output-path q2-picrust2_output/ko_exported

biom convert \
   -i q2-picrust2_output/ko_exported/feature-table.biom \
   -o q2-picrust2_output/ko_exported/feature-table.tsv \
   --to-tsv
The ECs:
qiime tools export \
   --input-path q2-picrust2_output/ec_metagenome.qza \
   --output-path q2-picrust2_output/ec_exported

biom convert \
   -i q2-picrust2_output/ec_exported/feature-table.biom \
   -o q2-picrust2_output/ec_exported/feature-table.tsv \
   --to-tsv
Authors
Authors: Robyn Wright, Monica Alvaro Fuss, Nidhi Gohil, André Comeau & Gavin Douglas
First created: 3 October 2018
Last updated: 29 October 2026
Based on initial versions by: Gavin Douglas (Amplicon SOP v2 (qiime2 2018.6), André Comeau (PacBio CCS Amplicon SOP v1 (qiime2)), and Robyn Wright Microbiome Helper 2 Marker gene workflow